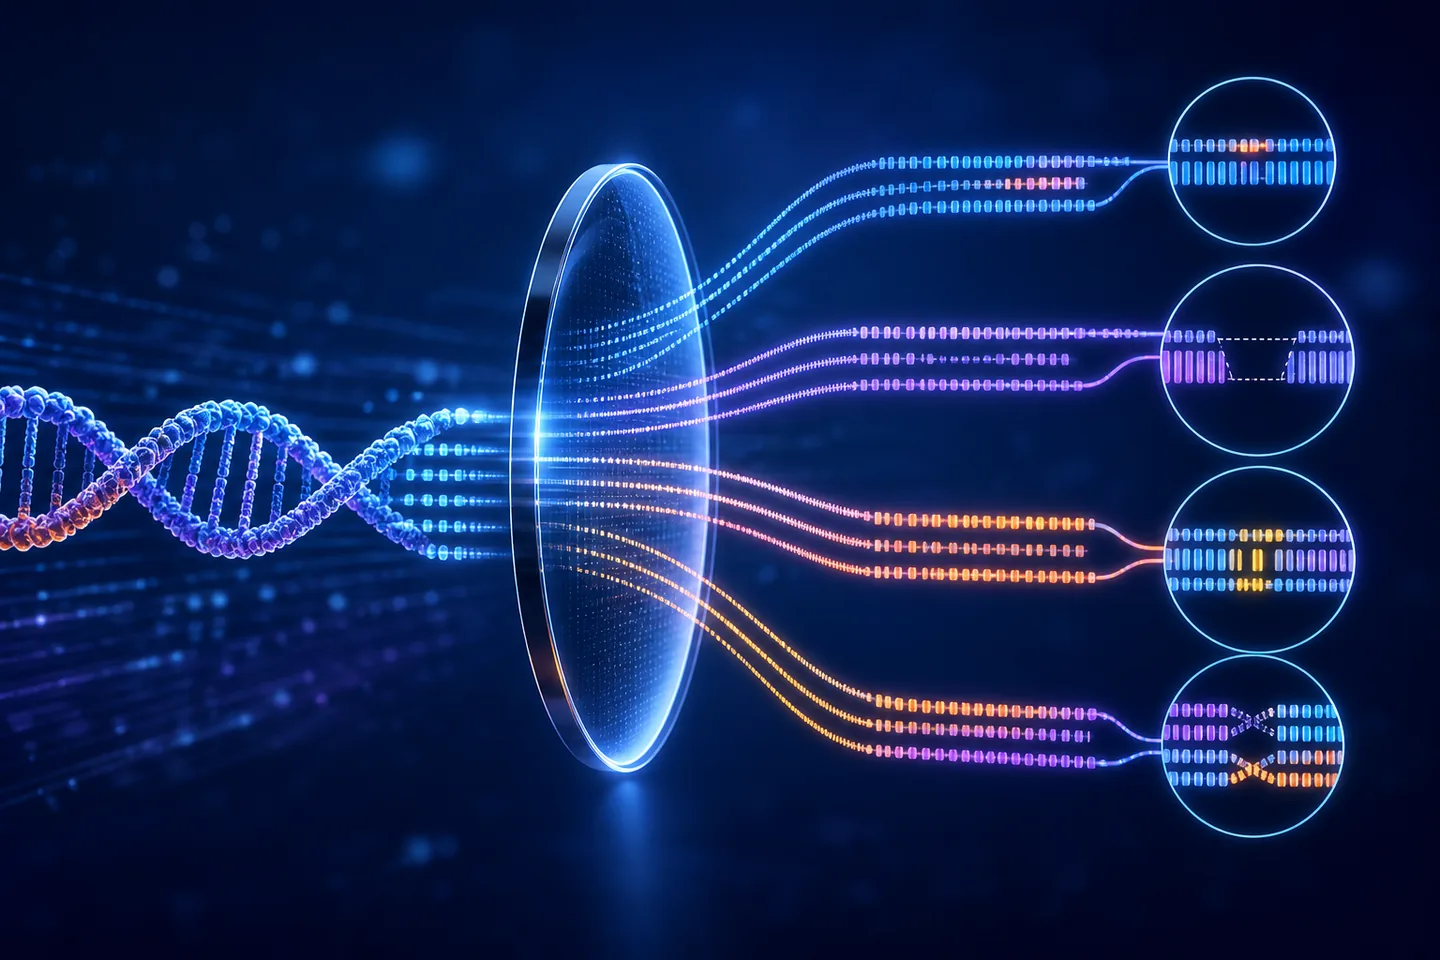
Researchers at Massachusetts General Hospital, Harvard Medical School and partner institutions have introduced CRISPRLungo, a computational pipeline for long amplicon reads from Oxford Nanopore and PacBio platforms. It combines unique-molecular-identifier error correction with statistical filtering to separate genuine editing events from PCR and sequencing noise.
The authors compared accuracy and read recovery on simulated datasets. The tool detected small insertions and deletions as well as larger structural variants, and flagged inversions in previously published datasets that earlier analyses had not reported. Selected quantitative measurements were confirmed with the independent ddPCR method.
A practical test analysed edited primary cells from a patient with Shwachman–Diamond syndrome. CRISPRLungo separated outcomes at the SBDS gene from contaminating reads of the highly similar SBDSP1 pseudogene. This was an analysis of laboratory data, not a clinical treatment trial or evidence of safety.
A possible use is more thorough quality control for experiments supporting gene therapies or disease models, allowing unexpected rearrangements at a target site to be found earlier. The code and a client-side web application are public, but the reliability of any conclusion still depends on experimental design, coverage and independent laboratory confirmation.
Routine use in regulated workflows will require prospective comparisons across laboratories, standard reference materials and clearly established detection limits. On an optimistic editorial estimate, CRISPRLungo or related methods could enter specialized research pipelines within 1–3 years; broader clinical standardization is likely to take longer, and this study does not establish that timetable.
Be the first to open the discussion.